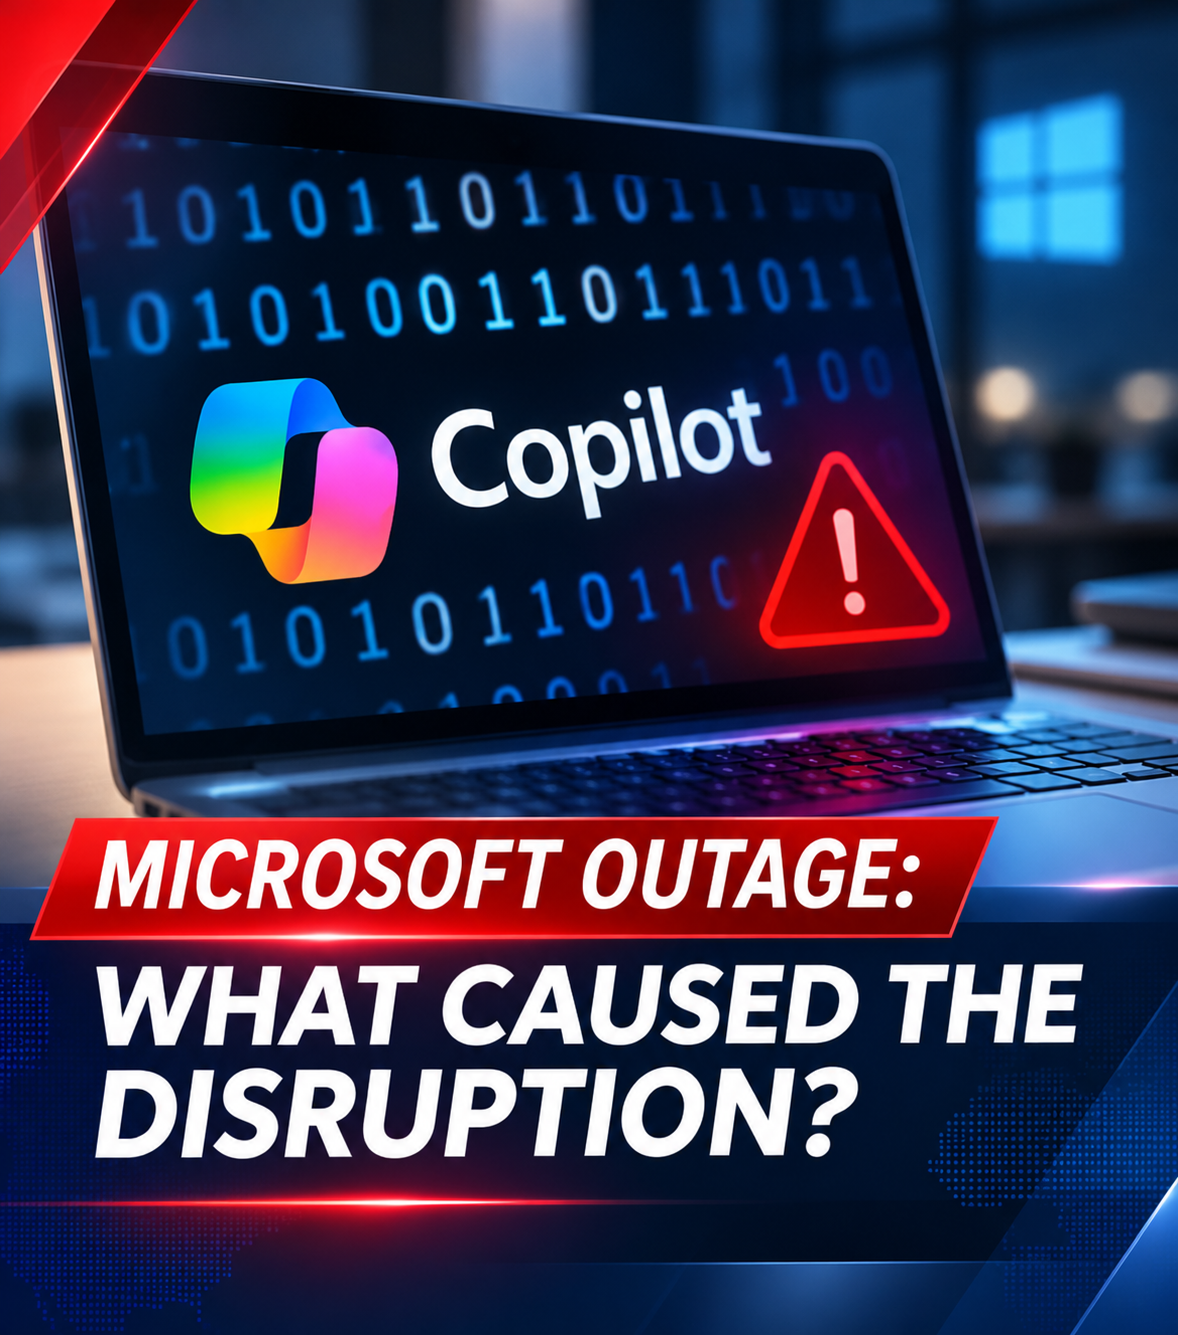
Several Microsoft services have experienced significant disruptions following what appears to be a server-related issue affecting the company’s infrastructure. Outlook has been among the most noticeably affected products, while other services, including Microsoft Teams and Copilot, have also experienced problems.
Initial explanations suggest that the disruption may be connected to the servers responsible for powering Outlook. However, the issue appears to have extended beyond a single application, raising questions about how Microsoft’s wider cloud infrastructure is handling the incident.
Microsoft Outlook at the Center of the Disruption
Microsoft Outlook appears to be one of the primary services affected by the outage. Users rely on the platform for email communication, scheduling, and everyday business activities, making any interruption particularly disruptive.
The reported problems have also extended to Microsoft Teams and Copilot. This wider impact suggests that the incident may involve interconnected infrastructure or systems supporting multiple Microsoft products rather than an isolated application failure.
Although the precise technical cause has not been fully established, the available explanation points toward difficulties involving the servers that support Microsoft’s online services.
Automated Error Systems May Have Contributed to the Problem
One possible explanation emerging from the incident involves Microsoft’s automated error detection and recovery systems.
These systems are designed to monitor infrastructure performance and respond when servers or network components experience problems. However, under certain circumstances, automated responses can potentially create additional complications rather than resolving the original issue.
The situation can be compared to a busy 10-lane motorway. If one lane closes, vehicles begin moving into the remaining lanes. A traffic control center might then decide to close another lane to manage the situation.
However, if this process continues repeatedly, more lanes become unavailable until traffic has nowhere to go. Instead of easing congestion, the automated decisions make the situation progressively worse.
A similar feedback loop may have developed within Microsoft’s infrastructure. If automated systems repeatedly respond to performance problems by restricting additional server capacity, the remaining infrastructure could face increasing pressure.
The Thundering Herd Problem: Why Recovery Can Be Difficult
Another important technical challenge associated with the disruption is known as the thundering herd problem.
This occurs when a large number of requests attempt to access a server or service simultaneously. It can happen when a system becomes available again after an outage and a backlog of waiting traffic suddenly tries to reconnect.
In Microsoft’s situation, the concern is that a substantial volume of requests may have accumulated while services were unavailable. When servers are brought back online, these requests could overwhelm the infrastructure before it has enough time to stabilize.
This creates a difficult recovery cycle. Servers become available, incoming traffic surges, and the additional demand may cause them to fail again. Each unsuccessful recovery attempt can make it harder to restore normal operations.
Why Restoring Microsoft Services May Take Time
Recovering from a large-scale infrastructure disruption involves more than simply restarting affected servers. Engineers may need to restore capacity gradually, manage incoming requests, identify the underlying technical problem, and prevent the same failure from happening again.
Traffic management techniques, including request throttling, load balancing, and controlled service restoration, can help reduce pressure on infrastructure during recovery.
However, the exact measures required depend on the underlying cause and the condition of the affected systems.
What Microsoft Users Should Know
For users experiencing difficulties with Outlook, Teams, or Copilot, the disruption highlights how interconnected modern cloud-based services can be.
A problem affecting one part of a technology provider’s infrastructure can potentially influence several applications that depend on shared systems.
Users who continue experiencing difficulties should check Microsoft’s official service health information for updates and avoid repeatedly sending requests if a service is responding slowly.
At this stage, the precise technical cause and the full extent of the disruption require further confirmation. The possibility that automated error-handling systems contributed to the incident remains an explanation rather than an established conclusion.
Conclusion
The reported disruption affecting Microsoft Outlook, Teams, and Copilot illustrates the challenges of maintaining large-scale cloud infrastructure. While server-related problems appear to be central to the incident, automated recovery mechanisms and the potential thundering herd effect may also complicate the restoration process.
As Microsoft works to restore affected services, the incident serves as a reminder that automated systems must be carefully managed to ensure that attempts to resolve technical failures do not create additional problems.